Building a Production LangGraph Travel Agent
How I built a LangGraph travel assistant that searches flights, hotels, and activities in parallel and assembles budget-aware packages.
First published in Python in Plain English
Update, October 2026: Two parts of this post no longer work as written. Amadeus shut down its Self-Service APIs on July 17, 2026, so the flight, activity, and Amadeus hotel searches need another provider. LangGraph also pauses and resumes runs with built-in interrupts now, which replace the
is_continuationworkaround in Challenge 4. What changed in 2026 covers both, along with streaming, durable execution and timeouts, MCP servers, agent checkout, prompt injection, budget math, and evaluation. I also redrew the diagrams.
A chatbot can answer a travel question. Planning a trip takes more:
- searching flights, hotels, and activities across several APIs at once
- turning a request like “5-day trip to Tokyo for $3000” into structured parameters
- collecting customer details partway through the conversation
- combining the results into packages that fit the budget
The target was a request like “Plan a 7-day honeymoon to Bali from NYC, departing May 15, budget $5000”, answered with options a customer could book. This post walks through how I built it with LangGraph. The code is on GitHub: langgraph-travel-agent.

The stack:
- LangGraph for workflow orchestration
- Gemini 2.5 Flash as the LLM
- Amadeus and Hotelbeds APIs for travel data
- FastAPI for the async backend
- React for a frontend that polls for results
How a request flows
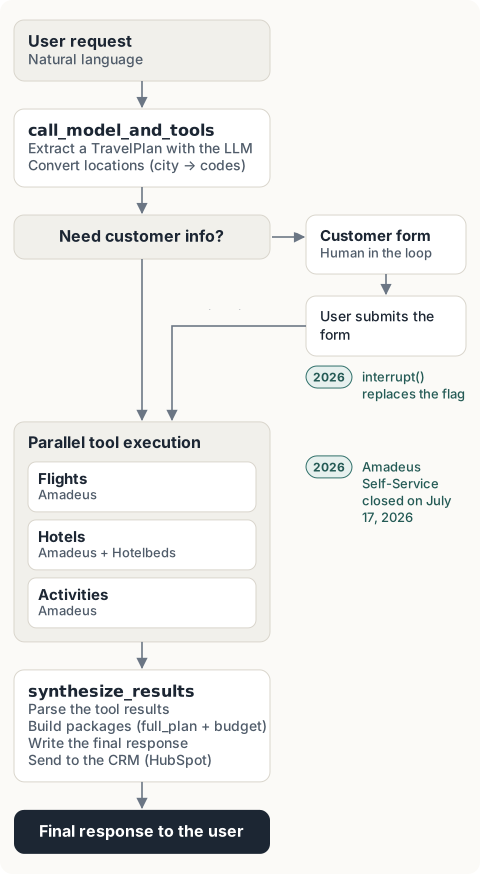
Five parts do most of the work:
- Human-in-the-loop (HITL): a customer-info form appears mid-conversation.
- Parallel tool calls: flight, hotel, and activity searches run at the same time.
- Two hotel providers: Amadeus and Hotelbeds are queried together.
- Packages: when the user gives a budget, the LLM builds Budget, Balanced, and Premium options.
- CRM handoff: the final plan goes to HubSpot.
Tools
Each tool is a LangChain @tool with typed inputs and outputs.
search_flights
- converts place names to airport codes (Tokyo → NRT)
- supports time windows such as morning or afternoon
- keeps the three cheapest flights, then re-sorts them by the preferred time
search_and_compare_hotels
- queries Amadeus (OAuth) and Hotelbeds (HMAC) in parallel
- returns about 40% more hotels than one provider alone
search_activities_by_city
- searches within 15 km of the city’s coordinates
- drops results that have neither a price nor a description
The intent extracted from the request decides which tools run:
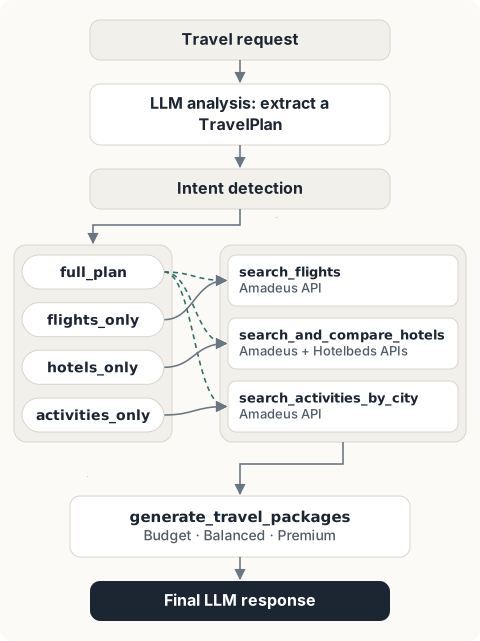
full_plan→ flights, hotels, and activitiesflights_only→ flightshotels_only→ hotelsactivities_only→ activities
State
| Field | Type | Purpose |
|---|---|---|
messages |
List[AnyMessage] |
Full conversation history (auto-accumulated) |
travel_plan |
TravelPlan |
Structured trip extracted by LLM (origin, destination, dates, budget, intent) |
customer_info |
Dict |
User details from HITL form (name, email, phone, budget) |
current_step |
str |
Workflow stage: "initial" → "collecting_info" → "synthesizing" → "complete" |
form_to_display |
str |
UI trigger: "customer_info" signals frontend to show form |
is_continuation |
bool |
Session flag: True after form submission to bypass re-collection |
original_request |
str |
First user message preserved for CRM context |
Challenge 1: From a sentence to a structured plan
Users write things like “I want to go to Tokyo next month.” The APIs need airport codes (NRT, HND), dates in YYYY-MM-DD, a numeric budget, and an intent. An LLM layer with Pydantic models fills that gap:
class TravelPlan(BaseModel):
    origin: Optional[str]
    destination: str
    departure_date: Optional[str]
    return_date: Optional[str]
    total_budget: Optional[float]
    user_intent: Literal["full_plan", "flights_only", "hotels_only", "activities_only"]
async def enhanced_travel_analysis(user_request: str) -> TravelPlan:
analysis_prompt = f"""
Extract structured trip information from: "{user_request}"
Today's date: {datetime.now().strftime('%Y-%m-%d')}
Output valid JSON matching: {TravelPlan.model_json_schema()}
"""
response = await llm.ainvoke(analysis_prompt)
return TravelPlan.model_validate_json(response.content)Putting the JSON schema in the prompt improved extraction accuracy: the model sees exactly which fields it has to fill.
Challenge 2: One city, three location formats
“Tokyo” means NRT or HND to a flight API, TYO to a hotel API, and (35.676, 139.650) to an activity API. A second LLM call converts names to codes:
async def location_to_airport_code(location_name: str) -> str:
    """Convert 'Tokyo' → 'NRT'"""
    if len(location_name) == 3 and location_name.isupper():
        return location_name  # Already a code

    conversion_prompt = f"""
    Convert this location to main airport IATA code.
    Examples: "Seoul" → "ICN", "Paris" → "CDG"
    Location: "{location_name}"
    IATA Code:
    """

    response = await llm.ainvoke(conversion_prompt)
    return response.content.strip().upper()
Origin and destination are converted in parallel. This adds about 200 ms and removes a hand-maintained mapping table.
Challenge 3: Parallel tool calls
Called one after another, the three searches take about 12 seconds. Run together, they take as long as the slowest one:
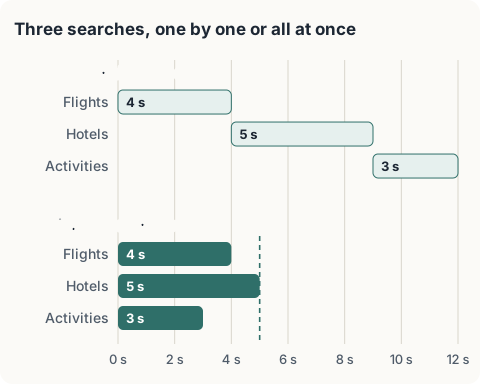
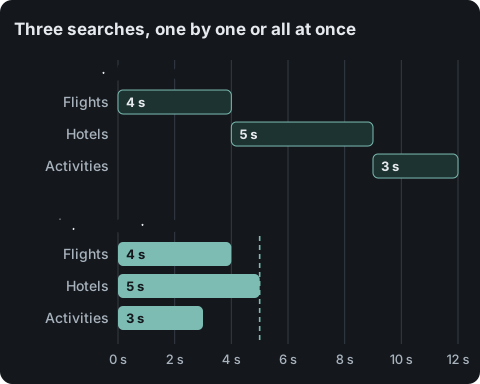
A LangGraph node runs them together with asyncio.gather():
async def call_model_node(state: TravelAgentState) -> dict:
    # Prepare all tool calls
    tasks = [
        search_flights.ainvoke({...}),
        search_and_compare_hotels.ainvoke({...}),
        search_activities_by_city.ainvoke({...})
    ]

    # Execute in parallel
    results = await asyncio.gather(*tasks, return_exceptions=True)
    # Convert to ToolMessages for LangGraph
    messages = []
    for result, tool_name in zip(results, tool_names):
        if isinstance(result, Exception):
            content = "[]"  # Handle failures gracefully
        else:
            content = json.dumps([item.model_dump() for item in result])
        messages.append(ToolMessage(
            content=content,
            name=tool_name,
            tool_call_id=f"call_{tool_name}"
        ))
    return {"messages": messages, "current_step": "synthesizing"}
The wait dropped from 12 seconds to about 5.
Challenge 4: Human-in-the-loop without losing state
The agent needs a name, email, and budget. Asking for everything up front is poor UX, and many agents cannot resume once they stop for input. Here the graph routes on a state field:
async def call_model_node(state: TravelAgentState) -> dict:
    # Check if we need customer info
    if (not state.get('customer_info') and
        state['current_step'] == "initial"):
        return {
            "current_step": "collecting_info",
            "form_to_display": "customer_info",
            "original_request": state['messages'][-1].content
        }

    # Otherwise, proceed with tools
    # ...
# Graph routing
workflow.add_conditional_edges(
    "call_model_and_tools",
    lambda state: state["current_step"],
    {
        "collecting_info": END,      # Pause for form
        "synthesizing": "synthesize_results",
        "complete": END
    }
)
The frontend shows the form when the status response asks for it, then resumes the run:
const response = await axios.get(`/chat/status/${taskId}`);
if (response.data.form_to_display === 'customer_info') {
    setShowCustomerForm(true);  // Display form
}

// After form submission
await axios.post('/chat/customer-info', {
    thread_id: threadId,
    customer_info: formData
});
// Resume with is_continuation=True
await axios.post('/chat', {
    message: originalRequest,
    thread_id: threadId,
    is_continuation: true  // Skip form check
});
The is_continuation flag matters. Without it, the resumed run asks for the form again and loops.
Challenge 5: Two hotel providers
Amadeus and Hotelbeds differ in authentication (OAuth vs HMAC), response schemas, and error behavior. Each sits behind its own function, and both run in parallel:
async def search_and_compare_hotels(
    city_code: str,
    check_in_date: str,
    check_out_date: str,
    adults: int = 1
) -> List[HotelOption]:

    # Convert location to city code
    actual_city = await location_to_city_code(city_code)
    # Search both providers in parallel
    results = await asyncio.gather(
        _search_amadeus_hotels(actual_city, check_in_date, check_out_date, adults),
        _search_hotelbeds_hotels(actual_city, check_in_date, check_out_date, adults)
    )
    # Combine results
    combined = []
    for provider_results in results:
        combined.extend(provider_results)
    return combined
Hotelbeds signs each request with a SHA-256 signature:
def _get_hotelbeds_headers():
    utc_timestamp = int(time.time())
    signature = hashlib.sha256(
        f"{api_key}{secret}{utc_timestamp}".encode()
    ).hexdigest()

    return {
        "Api-key": api_key,
        "X-Signature": signature,
        "Accept": "application/json"
    }
Adding Hotelbeds increased hotel coverage by about 40% over Amadeus alone.
Challenge 6: Packages that fit the budget
Five flights, eight hotels, and ten activities make 400 combinations, too many for one prompt. The agent sends a representative sample instead (the two cheapest, three mid-range, and two most expensive options) and asks the LLM for three tiers:
def _get_representative_options(options: List, max_items=7) -> List:
    """Sample cheapest, mid-range, and priciest options"""
    if len(options) <= max_items:
        return options

    options.sort(key=lambda x: float(x.price.split()[0]))
    return (
        options[:2] +           # Cheapest 2
        options[len(options)//2-1:len(options)//2+2] +  # Mid-range 3
        options[-2:]            # Most expensive 2
    )
async def generate_travel_packages(
    trip_plan: TravelPlan,
    all_options: Dict
) -> List[TravelPackage]:
    # Sample options to fit context window
    rep_flights = _get_representative_options(all_options['flights'])
    rep_hotels = _get_representative_options(all_options['hotels'])
    rep_activities = _get_representative_options(all_options['activities'], 10)

    generation_prompt = f"""
    Create 3 travel packages for budget ${trip_plan.total_budget}:

    Available options:
    - Flights: {json.dumps([f.model_dump() for f in rep_flights])}
    - Hotels: {json.dumps([h.model_dump() for h in rep_hotels])}
    - Activities: {json.dumps([a.model_dump() for a in rep_activities])}
    Requirements:
    - ONE flight, ONE hotel, 0-2 activities per package
    - Calculate: flight + (hotel × nights) + activities
    - Create Budget, Balanced, Premium tiers
    Output JSON array: {TravelPackage.model_json_schema()}
    """
    response = await llm.ainvoke(generation_prompt)
    return [TravelPackage.model_validate(p) for p in json.loads(response.content)]
Sampling cut prompt tokens by about 70% without hurting package quality.
Running it in production
Error handling
results = await asyncio.gather(*tasks, return_exceptions=True)

for result in results:
    if isinstance(result, Exception):
        print(f"Tool failed: {result}")
        content = "[]"  # Graceful degradation
    else:
        content = json.dumps([item.model_dump() for item in result])
A failed API returns an empty list instead of failing the whole request.
State persistence
InMemorySaver() is enough for development. Production needs Redis or Postgres.
from langgraph.checkpoint.memory import InMemorySaver

checkpointer = InMemorySaver()
graph = build_enhanced_graph(checkpointer)
# For production:
# from langgraph.checkpoint.redis import RedisSaver
# checkpointer = RedisSaver.from_conn_info(host="localhost", port=6379)
Background tasks and polling
A request takes 5–12 seconds, so the backend runs it as a background task and the frontend polls:
# Backend
@app.post("/chat")
async def start_chat_task(request: ChatRequest, background_tasks: BackgroundTasks):
    task_id = str(uuid.uuid4())
    jobs[task_id] = {"status": "running"}

    background_tasks.add_task(run_agent_in_background, task_id, request)
    return {"task_id": task_id}
@app.get("/chat/status/{task_id}")
async def get_task_status(task_id: str):
    return jobs.get(task_id, {"status": "not_found"})
// Frontend
const response = await axios.post('/chat', { message });
const taskId = response.data.task_id;
// Poll every 2.5 seconds
const interval = setInterval(async () => {
const status = await axios.get(`/chat/status/${taskId}`);
if (status.data.status === 'completed') {
clearInterval(interval);
displayResults(status.data.result);
}
}, 2500);What I learned
Keep nodes simple and branch with conditional edges
# BAD: Complex logic in node
async def node(state):
    if condition1:
        # do thing 1
    elif condition2:
        # do thing 2
    # ...
# GOOD: Simple node + conditional routing
async def node(state):
return {"current_step": determine_step(state)}
workflow.add_conditional_edges(
"node",
lambda state: state["current_step"],
{"step1": "node1", "step2": "node2"}
)Track the conversation stage explicitly
Human-in-the-loop flows loop forever without a flag like is_continuation.
Validate LLM output with Pydantic
# Instead of parsing LLM output manually:
response = await llm.ainvoke(prompt)
extracted = TravelPlan.model_validate_json(response.content)
Pydantic handles validation, error messages, and type coercion.
Run API calls in parallel
Sequential calls were the largest source of latency. asyncio.gather() removed most of it.
Sample instead of sending everything
The prompt does not need all 50 hotels. A spread of cheap, mid-range, and expensive options gives the model enough to choose from and stays within the token budget.
Numbers
Response time:
- analysis: 1–2 s
- parallel tool calls: 3–8 s
- package generation: 1–2 s
- total: 5–12 s
Cost per query with Gemini 2.5 Flash is about $0.001 for analysis and $0.002 for package generation, roughly $0.003 in total.
What changed in 2026
I added this section in October 2026, eleven months after the original post. Figure 5 sketches how I would rebuild the agent with what LangGraph and the travel ecosystem offer now. It is a design, not the deployed system; the subsections below explain each part.


Amadeus Self-Service is gone
In February 2026, Amadeus told developers it would stop accepting new registrations and decommission its Self-Service API portal for existing users on July 17, 2026. Enterprise customers keep access through the Amadeus Enterprise portal. The flight search, the Amadeus half of the hotel search, and the activity search in this post used Self-Service keys, so they stopped working on that date.
The design around them still holds. Each provider sits behind its own tool, a failure returns an empty list, and the hotel search merges providers. What changes is where the data comes from:
- Hotels: Hotelbeds still documents the signed-request scheme shown above.
- Booking.com: it runs a hosted MCP server for approved partners. The available tools depend on the affiliate account, and order creation isn’t included.
- Expedia: it has announced a B2B MCP server for partners.
- Google: it began testing agentic hotel booking in AI Mode in the US in August 2026 and plans to run it on its Universal Commerce Protocol (UCP). The first draft of UCP’s lodging-booking capability was published for feedback in September, and the hotel stays the merchant of record.
- Flights: Duffel sells self-serve flight search and booking on a pay-as-you-go plan, at $3 per confirmed order plus 1% of the order value when you use its accreditation. Otherwise you need an enterprise or consolidator contract, or a search-only fare API.
Interrupts replace the continuation flag
LangGraph 1.0 (October 2025) made pausing for a human a first-class feature:
- A node calls
interrupt(). - LangGraph saves the state through the checkpointer and waits.
- The client resumes the same thread with
Command(resume=...).
The value passed to resume becomes the return value of interrupt():
from langgraph.types import Command, interrupt

async def collect_customer_info(state: TravelAgentState) -> dict:
    if state.get("customer_info"):
        return {}
    form = interrupt({"form": "customer_info"})  # the run pauses; the client shows the form
    return {"customer_info": form}
config = {"configurable": {"thread_id": thread_id}}
await graph.ainvoke({"messages": [("user", request)]}, config) # stops at the form
await graph.ainvoke(Command(resume=form_data), config) # continues the same runThis removes form_to_display, is_continuation, and original_request from the state. The paused run keeps the original request in its checkpoint, and there is no flag to forget. Two rules from the docs matter here:
- On resume, the node runs again from its first line. Side effects such as the HubSpot call belong after the interrupt or in a later node.
- Don’t put
interrupt()inside a baretry/except, because it would catch the pause.
LangGraph 1.1 (March 2026) adds a typed return value. With version="v2", ainvoke returns a GraphOutput whose .interrupts field lists the pending pauses, instead of mixing them into the state under an __interrupt__ key. The status endpoint can pass the form request straight to the frontend:
result = await graph.ainvoke({"messages": [("user", request)]}, config, version="v2")
if result.interrupts:
    return {"status": "needs_input", "form": result.interrupts[0].value}
return {"status": "completed", "state": result.value}
LangChain 1.0 adds the same pause around tool calls. With HumanInTheLoopMiddleware, an agent built with create_agent stops before the tools you choose run, and a person can approve, edit, or reject the call. That fits the CRM handoff:
from langchain.agents import create_agent
from langchain.agents.middleware import HumanInTheLoopMiddleware

agent = create_agent(
    model=model,
    tools=[search_flights, search_and_compare_hotels, send_to_crm],
    middleware=[HumanInTheLoopMiddleware(interrupt_on={"send_to_crm": True})],
    checkpointer=checkpointer,
)
# Approve the pending call:
# agent.invoke(Command(resume={"decisions": [{"type": "approve"}]}), config)
Durable execution and a production checkpointer
LangGraph 0.6 added a durability setting that controls when checkpoints are written:
"exit"saves only when the run stops."async"writes in the background."sync"writes before each next step.
A booking flow should use "sync", so a crash can’t lose a step the user already confirmed. The LangGraph docs recommend Postgres for production:
from langgraph.checkpoint.postgres.aio import AsyncPostgresSaver

async with AsyncPostgresSaver.from_conn_string(DB_URI) as checkpointer:
    await checkpointer.setup()  # first run only
    graph = build_enhanced_graph(checkpointer)
    await graph.ainvoke(inputs, config, durability="sync")
LangGraph 1.2 (May 2026) adds the controls a graph that waits on outside suppliers needs:
- Per-node timeouts: a
TimeoutPolicyonadd_nodestops a hung supplier call. LangGraph discards that attempt’s writes and hands it to the retry policy. - Error handlers:
error_handler=runs after the last retry and can return aCommandthat routes to a fallback node, for example to release a held fare when a later step fails. - Graceful shutdown:
RunControl.request_drain()stops a run after the current step and saves a resumable checkpoint, so a deploy doesn’t cut a booking in half.
from langgraph.types import RetryPolicy, TimeoutPolicy

workflow.add_node(
    "search_flights",
    search_flights_node,
    timeout=TimeoutPolicy(run_timeout=20, idle_timeout=8),
    retry_policy=RetryPolicy(max_attempts=2),
    error_handler=use_cached_fares,  # returns a Command to a fallback node
)
Timeouts work on async nodes only.
Stream progress instead of polling
The frontend above polls every 2.5 seconds. LangGraph can stream instead:
stream_mode="updates"emits each node’s state change as it finishes."messages"streams LLM tokens."custom"carries anything a tool writes throughget_stream_writer(), such as “searching hotels…”.
Over server-sent events, the user sees each search arrive as it completes:
from fastapi.responses import StreamingResponse

@app.post("/chat/stream")
async def chat_stream(request: ChatRequest):
    config = {"configurable": {"thread_id": request.thread_id}}

    async def events():
        async for mode, chunk in graph.astream(
            {"messages": [("user", request.message)]}, config, stream_mode=["updates", "custom"]
        ):
            yield f"data: {json.dumps({'mode': mode, 'data': chunk}, default=str)}\n\n"

    return StreamingResponse(events(), media_type="text/event-stream")
LangGraph Platform, the hosted runtime, was renamed LangSmith Deployment in October 2025, and its API offers the same stream modes.
When the graph runs on LangGraph’s Agent Server (langgraph dev locally, or LangSmith Deployment), the useStream hook from @langchain/react replaces both the polling loop and the form flag on the frontend. It streams the run, exposes a pending interrupt, and resumes it:
import { useStream } from "@langchain/react";

const stream = useStream({ apiUrl: "http://localhost:2024", assistantId: "travel_agent" });
const pending = stream.interrupt?.value; // { form: "customer_info" } from interrupt()

// in the form's submit handler
stream.submit(null, { command: { resume: formData } });
Fan out with Send when the number of searches varies
asyncio.gather() is fine for a fixed set of three searches. A multi-city trip needs one flight search per leg, and the number of legs comes from the request. LangGraph’s Send creates one parallel branch per item, and a reducer on the state field merges the results:
import operator
from typing import Annotated

from langgraph.types import Send

class TravelAgentState(TypedDict):
    ...
    flights: Annotated[list, operator.add]  # branch results are concatenated

def plan_flight_searches(state: TravelAgentState):
    return [Send("search_leg", {"leg": leg}) for leg in state["travel_plan"].legs]

workflow.add_conditional_edges("call_model_and_tools", plan_flight_searches, ["search_leg"])
Here legs would be a new field on TravelPlan.
Do the budget math in code
Challenge 6 asks the LLM to add up flight, hotel, and activity prices and fit three tiers into the budget. Planning benchmarks show why that is fragile. In TravelPlanner (Xie et al., ICML 2024), GPT-4 produced a plan that met every constraint for 0.6% of the queries. When the LLM only translated the request into constraints and a solver searched for the plan, the success rate rose to 93.9%, and the solver could also say which constraint made an impossible request impossible (Hao et al., NAACL 2025).
This agent needs less than a solver. Five flights, eight hotels, and up to two of ten activities make about 2,200 combinations, which code can total, check against the budget, and sort in milliseconds. The LLM then only writes the descriptions:
from itertools import combinations

def package_total(flight, hotel, picks, nights):
    return flight.price + hotel.price_per_night * nights + sum(a.price for a in picks)

bundles = [()] + [(a,) for a in activities] + list(combinations(activities, 2))
options = sorted(
    ((package_total(f, h, picks, nights), f, h, picks) for f in flights for h in hotels for picks in bundles),
    key=lambda option: option[0],
)
affordable = [o for o in options if o[0] <= budget]
if affordable:
    tiers = {"Budget": affordable[0], "Balanced": affordable[len(affordable) // 2], "Premium": affordable[-1]}
Prices are parsed into numbers once, when the tool results come in. If nothing fits, the agent can report the cheapest total instead of inventing a package.
Keep supplier text away from the tools
Hotel and activity descriptions come from suppliers, and through MCP servers from third parties, so they can carry injected instructions. Beurer-Kellner et al. (2025) work through a booking assistant as one of their case studies. In their most robust design, a privileged LLM fixes the plan from the user’s request alone, and third-party content goes to a separate LLM that has no tools. Applied to this agent:
- the step that reads supplier text and writes the packages runs without the CRM or booking tools
- tools with side effects, such as the HubSpot call or a booking, stay behind
HumanInTheLoopMiddleware - the customer’s details go only to the step that needs them
Models and cost
Gemini 2.5 Flash still runs for projects that already used it, but Google now points new projects to Gemini 3.8 Flash or Gemini 3.5 Flash-Lite. The cost figures above were measured with 2.5 Flash, so measure them again with the current model.
MCP servers and agent checkout
Travel companies now expose inventory to agents directly:
- Kiwi.com: released a prototype MCP server for flight search in August 2025.
- Expedia and Booking.com: launched apps inside ChatGPT on OpenAI’s Apps SDK, which is built on MCP.
- Booking.com: also runs the partner MCP server mentioned above.
An agent like this one can call those servers instead of wrapping each REST API by hand. LangChain 1.4 (September 2026) builds the client into LangChain: MCPAdapter in langchain.mcp, in beta, replaces the separate langchain-mcp-adapters package and turns a server’s tools into LangChain tools.
from langchain.agents import create_agent
from langchain.mcp import MCPAdapter

async with MCPAdapter("https://partner.example.com/mcp") as adapter:
    supplier_tools = await adapter.list_tools()
agent = create_agent(model, supplier_tools + [send_to_crm], checkpointer=checkpointer)
Two details fit this agent. When a server asks the user a question in the middle of a call, the adapter turns it into a LangGraph interrupt, so the same pause-and-resume path handles it. Each tool also carries the server’s annotations, such as destructive_hint, which can decide which calls need approval.
MCP Apps, the first official MCP extension (January 2026), lets a server return an interactive UI that hosts such as Claude, ChatGPT, Goose, and VS Code render in a sandboxed frame. A customer form like the one in Challenge 4 can now ship with the server instead of with every frontend.
Checkout is following:
- OpenAI and Stripe released the Agentic Commerce Protocol with Instant Checkout in ChatGPT in September 2025.
- Google published the Agent Payments Protocol (AP2) the same month, and in January 2026 launched the Universal Commerce Protocol (UCP) with Shopify and large retailers. UCP works alongside AP2 and is now being extended to hotel booking.
The HubSpot handoff in this post ends at a lead. With these protocols, the same flow could end at a booking, with an approval step before any payment.
Evaluate against τ²-bench
τ²-bench (Barres et al., 2025) tests conversational agents in environments where both the agent and a simulated user can act on shared state. Its airline domain has 50 tasks carried over from the original τ-bench and is close to the booking and change requests this agent would handle. Amazon’s τ²-Bench-Verified fixes tasks whose expected actions did not match the policies, so check which version a reported score uses. For the planning side, TravelPlanner, described above, checks whether a plan respects every constraint in the request.
Where the LangChain stack went
LangChain 1.0’s create_agent runs on LangGraph, and the Deep Agents harness adds planning, a file system, and subagents for long, open-ended tasks. In August 2026 LangChain launched Managed Deep Agents, which bundles that harness with LangSmith Deployment, sandboxes, memory, and authentication. This agent follows a fixed workflow, which maps directly onto a LangGraph graph. The deep-agent stack targets open-ended work, such as researching and revising a multi-city itinerary over many steps.
Next steps, revisited
Two of the next steps below now have built-in support:
- Caching repeated searches: node caching (
cache_policy=CachePolicy(ttl=...)onadd_node, with a cache passed tocompile) returns the stored result for the same input until the TTL expires. - Learning from the packages users pick: LangGraph’s store keeps memory across threads, such as a traveler’s preferred hotel class, in memory or in Postgres.
Sources for this update
- PhocusWire: Amadeus to shut down self-service APIs portal for developers (February 2026)
- LangGraph: interrupts, durable execution, persistence, streaming, and what’s new in v1
- LangChain: human-in-the-loop middleware
- Gemini API models
- Booking.com MCP server, Hotelbeds API docs
- Kiwi.com MCP server prototype, Skift: Expedia B2B MCP
- Stripe: Instant Checkout and the Agentic Commerce Protocol, Google Cloud: AP2
- τ²-bench (arXiv:2506.07982), τ²-Bench-Verified
- LangChain changelog: LangGraph 1.1 and 1.2, LangChain 1.4, fault tolerance, node caching
- LangChain MCP, MCP tools, elicitation, and approval, frontend human-in-the-loop with useStream
- MCP Apps (January 2026)
- Duffel pricing, Skift: Google confirms agentic hotel booking is in testing, Google: UCP for lodging, Search Engine Journal: Google plans to adopt the UCP lodging draft, InfoQ: Google’s Universal Commerce Protocol
- TravelPlanner (arXiv:2402.01622), Hao et al., NAACL 2025
- Design Patterns for Securing LLM Agents against Prompt Injections (arXiv:2506.08837)
- LangChain: why managed agents (August 2026)
Next steps
- A Redis cache for repeated searches
- Learning from the packages users pick
- Follow-up requests such as “show me cheaper hotels”
- Car rentals, to cover the whole trip
The full implementation is on GitHub: langgraph-travel-agent.