Document AI OCR
Document AI for HWP and PDF notices · key-field F1 0.985 · about 2,000 notices/day
Built withPython · HWP/HWPX · PDF · Gemini 2.5 Flash-Lite · ThreadPool · Deterministic parsing
WHY
Key inputs for model training and joint-bid matching, such as discipline shares and construction-capacity criteria, existed only inside attached HWP and PDF notices rather than in the listing API. Manually opening about 2,000 new notices each day could not support real-time feature creation or client matching. The required system had to structure those documents automatically while keeping every amount and ratio reproducible.
HWP/HWPX and PDF procurement notices
New notices processed automatically
Amounts, ratios, and units validated in code
HOW
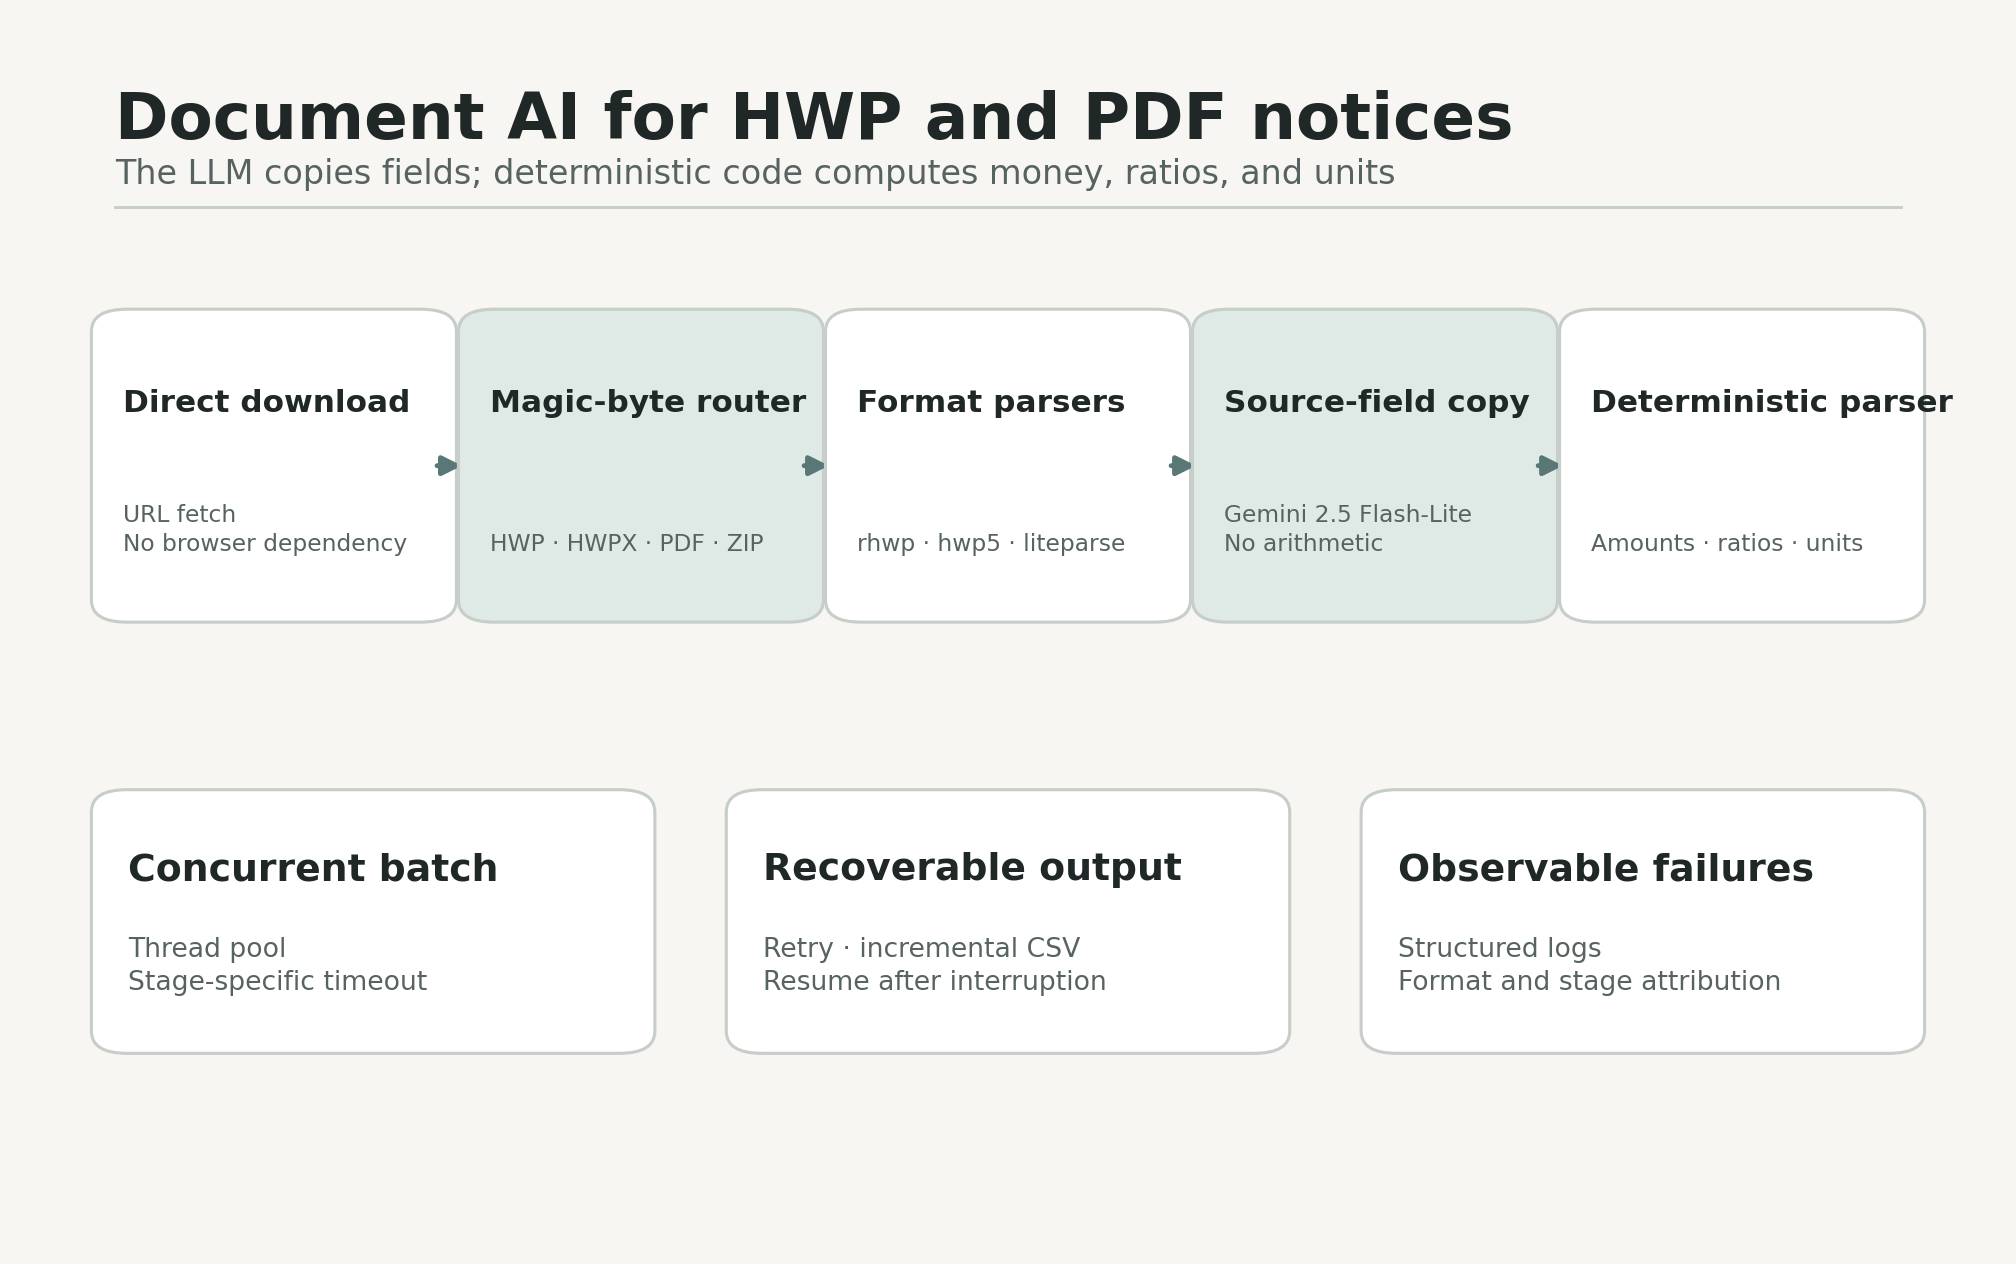
Separate document recovery, field copying, and arithmetic
Each stage has one responsibility, making extraction errors observable and numeric outputs reproducible.
- 01Direct download
Fetch the source URL without browser automation and retain the original bytes.
- 02Format routing
Use magic bytes to distinguish HWP, HWPX, PDF, and ZIP rather than trusting the filename.
- 03Text recovery
Apply rhwp, hwp5, or liteparse through format-specific paths with bounded retries.
- 04Source-field copy
Ask Gemini 2.5 Flash-Lite to copy fields from the recovered text without calculation.
- 05Deterministic calculation
Parse amounts, ratios, and units in code, then append structured output and error logs.
RESULT
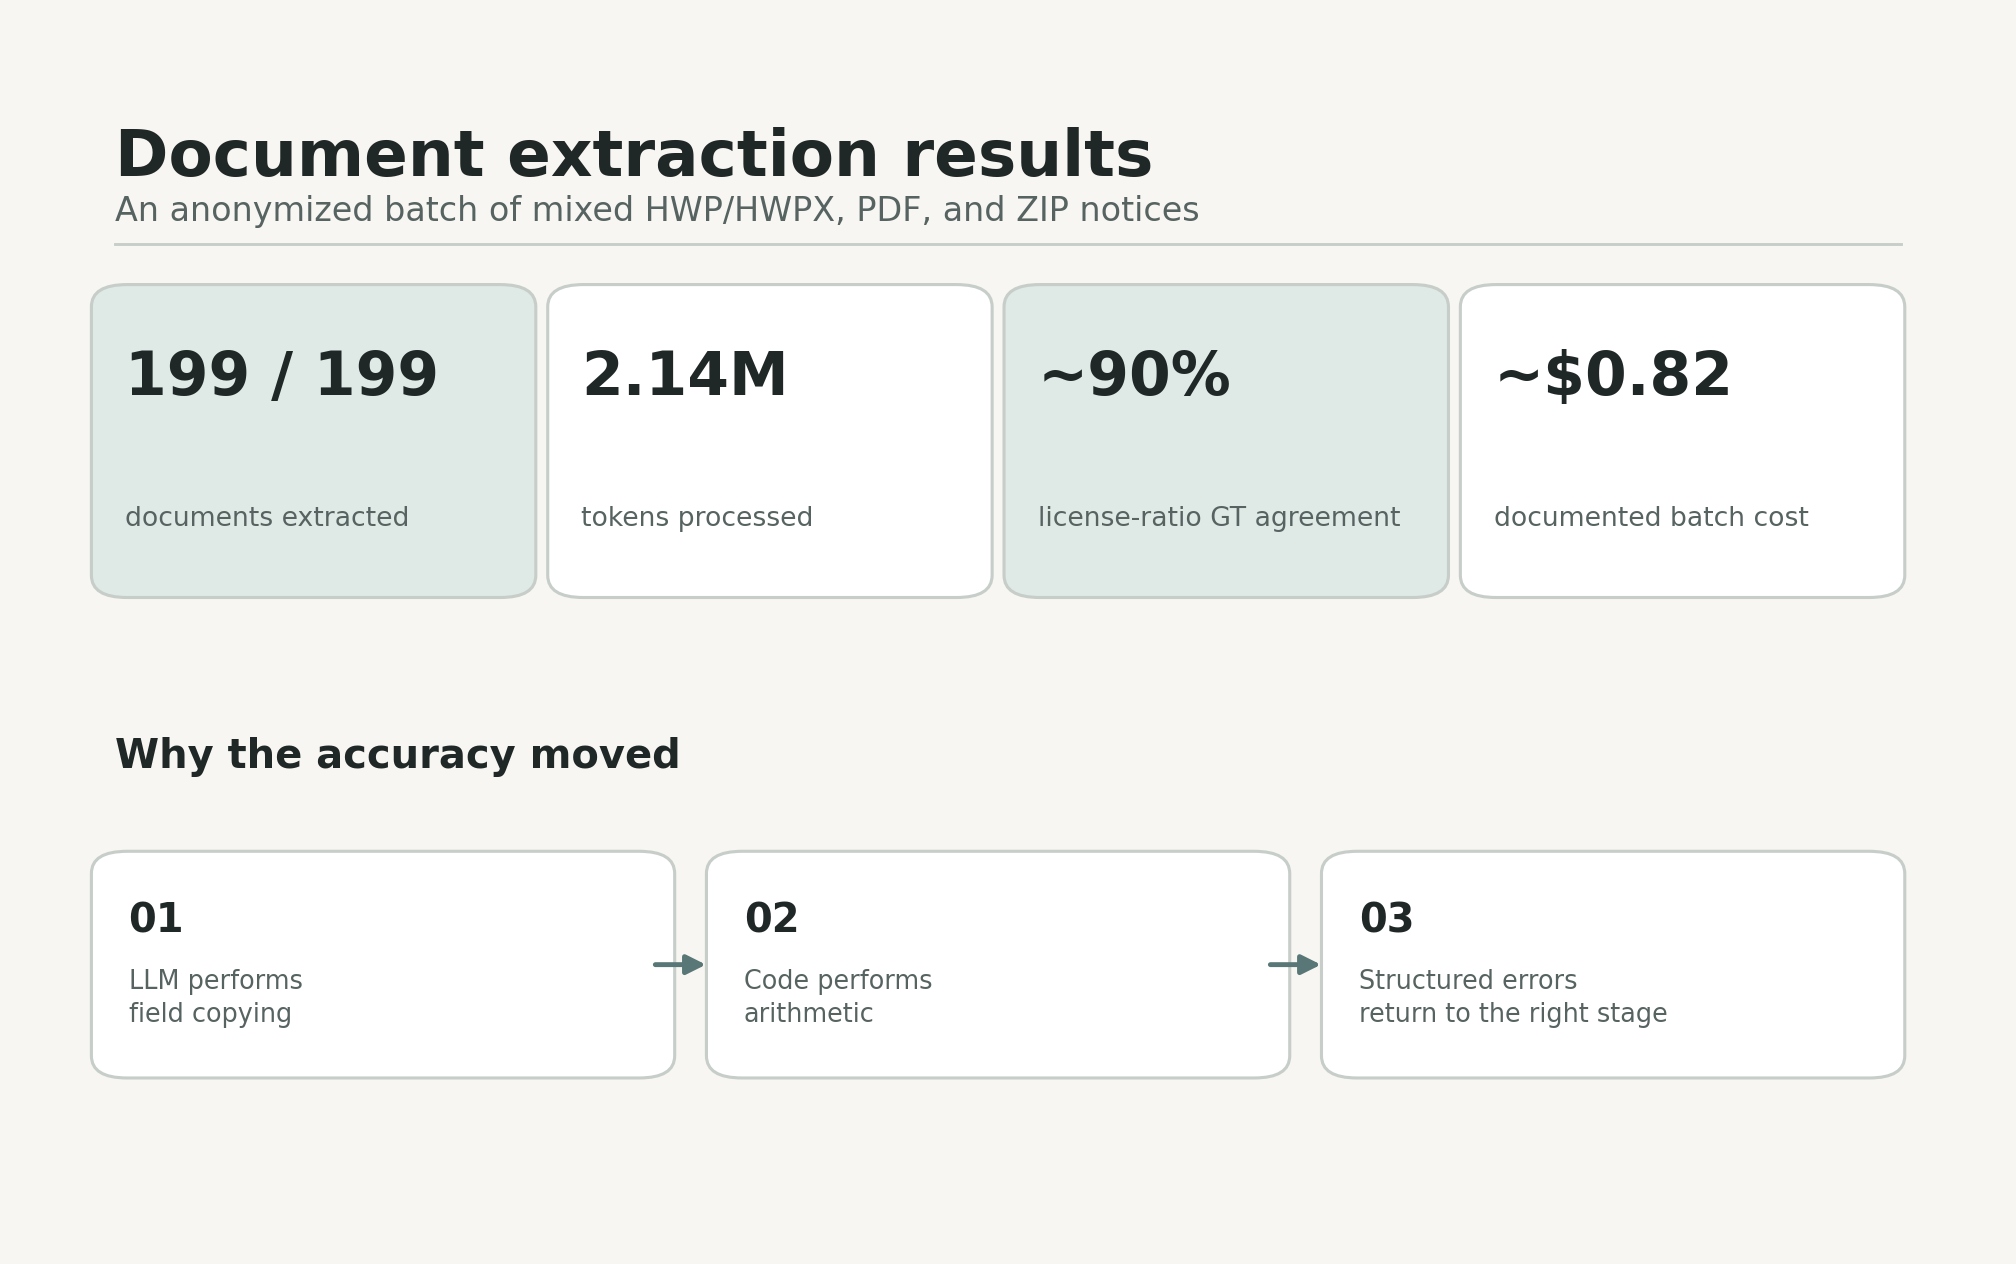
Measured extraction batch
| Measure | Result | Why it matters |
|---|---|---|
| Documents | 199 / 199 | No failed extraction in the measured batch |
| Content | 2,140,021 tokens | Large documents preserved instead of reduced to snippets |
| License-ratio GT | About 90% | Deterministic ratio handling after source-field extraction |
| Documented cost | About $0.82 | Batch-scale use of a lightweight model |
Contribution
- Designed the direct-download, magic-byte routing, parser fallback, and deterministic numeric-processing boundary.
- Built concurrent batching with stage-specific timeouts, retries, incremental CSV output, and structured error attribution.
Evidence
Private project